AngryTechnician
-
Posts
3,772 -
Joined
-
Last visited
Content Type
Forums
News
20th
EduGeek EDIT Conference
Blogs
Everything posted by AngryTechnician
-
I'm 99% sure it's a horrible coincidence. Without changing DNS records I see no way that Google Apps can affect your on-premises email.
-
Logins: you'll get login pages with addresses that look like this: http://mail.google.com/a/yourschool.com/ When using those links, users will only need to enter the username, not the full @Yourschool.com address. Alternatively they can use the normal login pages for Gmail etc and just use their full email address. If you control the A records for your domain, you can also create subdomains such as webmail.yourschool.com that will redirect to the above addresses. Verifying your domain: basically things won't work right until you do this. You can do it either by making a new DNS record or putting a special file on the root of your website. If done correctly it should not affect the running of your website at all. On-site Exchange: if you don't want to use Gmail at all for any users, you can simply turn it off in the Google Apps control panel. Even if you leave it on, no mail will be delivered to it anyway unless you change your MX DNS records. If you want Gmail for some users but still use Exchange for others, it's a bit more complicated, but still completely possible.
-

Meraki via Smoothwall Express 3.0
AngryTechnician replied to sahilkhan's topic in Internet Related/Filtering/Firewall
That is the exact opposite of what a Meraki engineer told me. It uses other ports as well, but it does use port 80 and 443 as referenced on the document you linked - what is it using them for if not HTTP and HTTPS? -
Meraki via Smoothwall Express 3.0
AngryTechnician replied to sahilkhan's topic in Internet Related/Filtering/Firewall
First you need to set up the Smoothwall Express to work in transparent mode via the config pages, then you need to set the green interface IP of the Smoothwall as the default gateway on every device you want to go through it. If you're just sending the Meraki through it, you only need to change the default gateway for the APs and can leave the rest of your network alone. My advice would be to make DHCP reservations for each AP and then configure the default gateway on each reservation. It's DHCP option 003 (labelled Router on Windows DHCP servers). If you are using VLANs you can also do it on the DHCP scope for that VLAN. -
Windows 8 Enterprise on Volume Licensing Site
AngryTechnician replied to jamesmay's topic in Windows 8
Has anyone got their Windows 8 KMS key through the VLSC site directly? We have SA and Windows 8 is listed under our licensed products, but when I go to get the key all I see is this:
-
Ghost Woes with Dell Latitude ST Tablet
AngryTechnician replied to RabbieBurns's topic in Enterprise Software
I use WDS rather than SCCM (which I detest) so not my area of expertise. I will say though that BIOS version A05 is now available. Not that it stops the ST being pants. Yesterday mine wouldn't even power on after going into hibernate, and was so badly stuffed I had to dismantle it and detach the internal battery to reset it. I would never buy another one of these, and I will be thinking twice about buying any future tablets from Dell. -
I didn't install the update to solve any slow login problems - we weren't affected by that particular issue. I installed it to get the other cumulative fixes in GPP. It isn't the Microsoft-recommended way to go about things, but until they release a new official cumulative update for GPP, that's what I do. There are a lot of reasons login could be slow besides Group Policy Preferences. Do you have verbose logon messages enabled to see which bit is slow?
-
Does that HP server have a LOM card in it? They usually require their own IP address independent of the server. Not sure why it wouldn't be picking one up though.
-
Create subfolders by typing the subfolder name at the start in the Name field, e.g. "Office\Word 2010". To delete folders, simply use the Folders section of GPP.
-
GPP is still buggy as hell, even in SP2; my advice is always to apply the latest GPP hotfix as you get all the cumulative fixes since SP2 (and there are a lot). The one I have installed and works is this one: You experience a long domain logon time in Windows 7 or in Windows Server 2008 R2 after you deploy Group Policy preferences to the computer I think the latest though is this one, and has fixes for printer issues that look familiar so I'll probably roll it out myself soon: Group Policy Preferences stops responding when you try to configure printers that use third-party drivers in Windows Server 2008
-
Agree, KMS. We do in fact have a member of staff who hit the 180 day limit and never even noticed because they didn't turn the laptop on for 8 months. I called it in for "servicing". They're not getting it back.
-
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
Touché. -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
Firmware is the latest, last update was in May 2010 so not expecting any further updates. I already have a way around not being able to route the IPTV (the other VLANs will get a unicast stream instead) so I'm not going to lose any more sleep over it, but it would have been nice to know the switch was rubbish before spending a week growing grey hairs trying to figure it out! -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
Right, well I've had a thoroughly frustrating day with this, but I have some answers. It's definitely a problem with the multicast traffic combined with ip multicast-routing. I must have left it on initially when I thought I had ruled it out, because I've been able to literally toggle the problem on and off today by enabling and disabling multicast-routing while having a PING running. The problem occurs even if PIM is disabled, so the multicast traffic isn't even being routed - just the presence of multicast traffic on a single VLAN with routing on is enough. If I have multicast-routing on with no multicast traffic: everything is fine. If I have multicast traffic with no multicast-routing: everything is fine. If I have even the slightest amount of traffic (as little as a single SAP announce) with multicast-routing on, the problem will occur. Another tell-tale symptom I've discovered today is that when the multicast is being routed, the routing performance is poor. SD streams are OK, but on anything but the default VLAN, HD streams are garbled with MPEG decoding artefacts on playback. That doesn't happen on the default VLAN (where the traffic originates), even when testing from the farthest point of the topology over a wireless WDS bridge. There are documented limits for multicast routing on this switch, which get easier to reach the more VLANs you have, and at one point I had thought it might be a load problem due to the amount of multicast traffic. Then when it happened with just the SAP announcements running, which are a tiny amount of text traffic on a single multicast address, I came to the conclusion that the ProCurve 5300 series is just a pile of junk. There are no pertinent messages logged to the debug log when the problem occurs (even with debug all), and there was nothing unusual shown on a monitoring port trace using Wireshark. The switch simply doesn't do what its supposed to. Thanks for all your help and suggestion guys, it has helped me narrow down the issue and preserve my sanity. I will be having an interesting chat next time our local ProCurve specialist calls to make a sale. -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
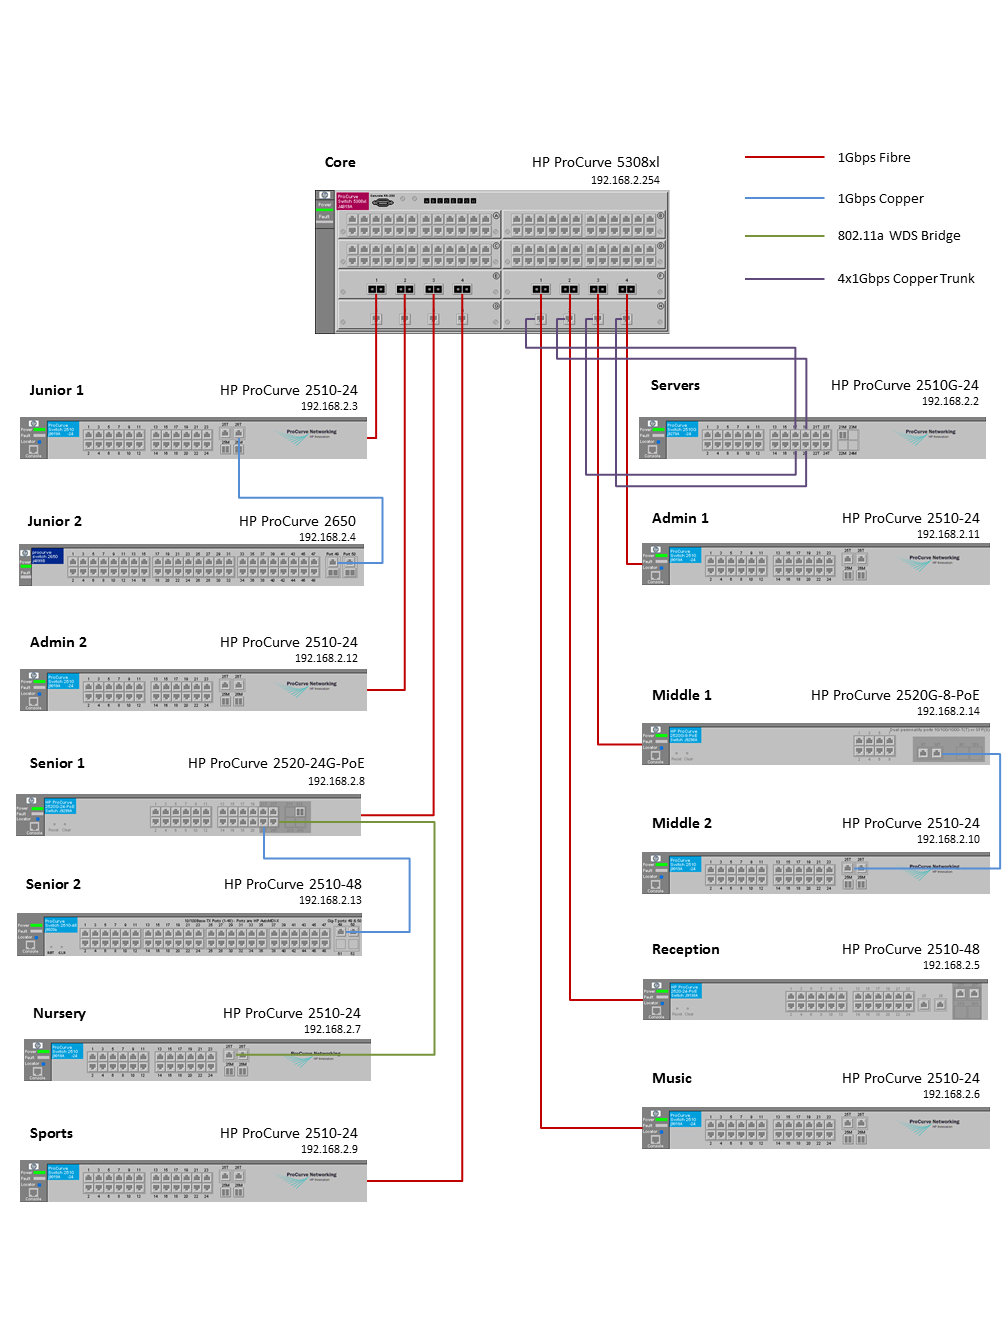
OK, the multicast server remained off yesterday as I was doing a lab build all day, but there still seem to be no recurrences of the problem. I plan to fire it back up tomorrow when no-one else is in to reproduce the issue and do some more troubleshooting. I know the details of the multicast IPTV server extremely well as it's a personal project. It has been running pretty much 24/7 for 2 years with no issues, so it's a little odd that it's suddenly causing problems now. IGMP is configured on all switches on the VLANs which carry the IPTV: with ~100Mbps of multicast traffic being pumped out by the IPTV, it's very obvious from the traffic graphs if you miss a switch (as I have once in the past). It broadcasts SAP on the normal 224.2.127.254 address, and the ITPV channels are on the following addresses: 239.255.0.1 239.255.0.10 239.255.0.11 239.255.0.12 239.255.0.14 239.255.0.15 239.255.0.18 239.255.0.19 239.255.0.2 239.255.0.21 239.255.0.24 239.255.0.28 239.255.0.3 239.255.0.30 239.255.0.31 239.255.0.38 239.255.0.4 239.255.0.46 239.255.0.47 239.255.0.49 239.255.0.5 239.255.0.50 239.255.0.51 239.255.0.52 239.255.0.54 239.255.0.6 239.255.0.7 239.255.0.70 239.255.0.71 239.255.0.72 239.255.0.80 239.255.0.81 239.255.0.82 239.255.0.85 239.255.0.87 239.255.0.89 239.255.0.9 239.255.1.5 239.255.3.1 239.255.7.1 239.255.7.10 239.255.7.100 239.255.7.11 239.255.7.12 239.255.7.13 239.255.7.14 239.255.7.15 239.255.7.16 239.255.7.18 239.255.7.2 239.255.7.22 239.255.7.23 239.255.7.24 239.255.7.27 239.255.7.28 239.255.7.3 239.255.7.4 239.255.7.5 239.255.7.6 239.255.7.7 239.255.7.8 239.255.7.9 Unless I've missed something, the IPTV streams are all in the administratively scoped multicast address space, and there are no other multicast servers on the network (aside from the WDS server, but I never use the multicast features). I've attached a switch topology graphic. The only time I have more than one connection between any two switches is between the core and the switch immediately below it in the rack for my servers. The 4 links are trunked, and there are no reported errors with that so it is acting as a single 4Gbps link. At this point I'm beginning to wonder if this switch just can't hack that much IGMP/multicast and the routing at the same time, regardless of whether the traffic is to-standard or not. The CPU and memory aren't getting much above 50%, but it wouldn't be the first problem I've had with sub-par performance from HP kit.
-
Can you have a look at the C:\Windows\WindowsUpdate.log and see if there is any mention of the update you've published and approved?
-
Recovering a Server 2008 R2 software RAID partition
AngryTechnician replied to SST's topic in Windows Server 2008 R2
By software RAID, I assume you mean using Dynamic Disks? If so, I'm pretty sure that you just need to reattach all the disks and you can then mount the RAID array using Disk Management (I recall having done it myself once before). This page has a description of the procedure: Move Disks to Another Computer Of course, having a bare-metal backup of the OS drive is always a good idea too in my book. -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
I don't have any ACLs yet, so I don't think I can configure any more logging than what I'm already getting from show logging, can I? I do know that DNS is fine - I can always resolve names to IPs. One notable development: since turning off the IPTV server last night, I haven't had the problem once. Going to leave it off for the rest of the day, especially as I haven't been using my workstation intensively this morning, but we could be on to something here. I already know that the problem was happening before multicast-routing was enabled, but could just having the multicast traffic there in the first place cause something like this? I've had this IPTV box running for 2 years without any issues before turning on L3. -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
Thing is, when I lose access to a a website (e.g. EduGeek), I still get access to other websites (e.g. BBC) and I can still ping our Internet gateway, AND the site is still pingable from the switch via telnet. Unless I drastically misunderstand STP, isn't the only way STP could block websites is if it blocked the port the gateway was on, which would affect all websites simultaneously, and even the switch wouldn;t be able to get through? I've checked the logs and they don't indicate any ports being blocked. When a client fails, it can still ping it's gateway IP. I will take a careful look at which ports a MAC address is resolving to when this happens as @CyberNerd suggests, but I'm fairly sure I've looked at this already when websites have been affected and the gateway MAC appears on the same port every time. Will look closely at what happens when it's a LAN address. @Destinova: What sort of multicast issues are you suspicious of? I do have a multicast IPTV server running (though I actually shut it off temporarily last night as I began to scrape the bottom of the barrel for ideas of what the problem could be). When it's running, it's on a separate VLAN to the iSCSI and there is no routing in or out of the iSCSI VLAN. -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
@CyberNerd: A loop had crossed by mind already - wouldn't STP catch that? I have it enabled on all switches. And wouldn't I have seen problems before enabling L3 routing? @DMcCoy: Will have a look at mac-age-time tomorrow, thanks. @Abaddon: Hopefully he won't charge you extra for looking at someone else's problems, but thanks! -
What's wrong with my ProCurve 5308xl (or its config)?
AngryTechnician replied to AngryTechnician's topic in Wired Networks
Firmware is the latest (E.11.21). Have done a reload a couple of times now and the problem remains. -
Last weekend I finally got around to setting up Layer 3 routing on my core switch (a ProCurve 5308xl) and re-addressed the entire network to split it up into sensible(?) VLANs, with 1 subnet per VLAN, and the switch routing traffic between them. Since then, everything works perfectly about 95% of the time: clients pick up DHCP addresses, everything uses the switch as the default gateway, and traffic passes to and fro normally. Then every so often (once an hour or so?), something inexplicable happens. Basically, the switch will suddenly decide it cannot route to some (but not all) addresses from one VLAN to another. Example 1: I'm sitting on a client on VLAN 6, and I'm browsing BBC News (via our gateway router on VLAN 7). Then I go to EduGeek and find it won't load. I start a PING, and this is what I see: Pinging www.edugeek.net [176.9.42.234] with 32 bytes of data: Request timed out. Request timed out. Request timed out. Request timed out. Request timed out. Request timed out. Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Reply from 176.9.42.234: bytes=32 time=40ms TTL=55 Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Reply from 176.9.42.234: bytes=32 time=41ms TTL=55 Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Reply from 176.9.42.234: bytes=32 time=40ms TTL=55 Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Reply from 176.9.42.234: bytes=32 time=39ms TTL=55 Basically, after less than a minute of PING, the remote address will start responding and everything works again. It always comes back quite quickly; so far I've never had a delay of more than about a minute. It will then be fine again for some time - hours or more - before the exact same thing happens again, maybe with the same address, maybe with a different one. It's like it just forgets how to reach an address, then after nagging it for a minute or two, it suddenly remembers and starts passing traffic. This also happens (less frequently) with LAN addresses, so it's not just Internet routing that is affected. Basically, anything that has to cross to a different VLAN or be routed out by the switch seems to be at risk, but not in any pattern I can identify. Here's what my investigations have uncovered so far: At all times when this is happening, I can initiate a PING from the core switch via a telnet console session, and the affected address responds to the switch instantly, while still not responding to the client. I can always PING other addresses in the same subnet/VLAN as the client, including the switch, which is acting as the default gateway for each subnet. It seems to be only individual addresses that are affected at any one time, rather than whole VLANs or subnets: I've had instances where I can't ping 192.168.2.1, but I can ping 192.168.2.2. When an address becomes unreachable, it becomes unreachable for ALL clients on all all VLANs (including the default VLAN) simultaneously, except for the core switch (which can always reach everything). I can't tell if it literally only affects a single IP at a time. I don't think I've had a situation yet where multiple addresses are affected, but it lasts for such a short time that it's tricky to do much testing before the problem disappears again. After 2 days of poring over forums and switch config, I am almost at my wit's end. This switch has been in use without L3 without any issues, suggesting its something to do with my config, but I can't work out what, especially as it works as designed most of the time. Here is the config I'm using: ; J4819A Configuration Editor; Created on release #E.11.21 hostname "Core" max-vlans 16 time daylight-time-rule Western-Europe module 7 type J4821A module 8 type J4821A module 6 type J4878A module 4 type J4820A module 3 type J4820A module 1 type J4820A module 2 type J4820A module 5 type J4878A interface H1 no lacp exit interface H2 no lacp exit interface H3 no lacp exit interface H4 no lacp exit trunk H1-H4 Trk1 LACP sntp server 192.168.3.1 ip routing ip udp-bcast-forward timesync sntp sntp unicast snmp-server community "public" Unrestricted vlan 1 name "DEFAULT_VLAN" untagged A1-A5,A7-A24,B1-B5,B7-B10,B12-B15,B17-B24,C3-C24,D1-D21,D23,E1-E4,F1 -F4,G2-G3,Trk1 ip address 192.168.11.254 255.255.252.0 ip helper-address 192.168.3.22 no untagged A6,B6,B11,B16,C1-C2,D22,D24,G1,G4 ip igmp exit vlan 50 name "iSCSI" no ip address tagged F2,Trk1 exit vlan 100 name "NM" ip address 192.168.100.254 255.255.255.0 ip helper-address 192.168.3.22 tagged E1-E4,F1-F4,G3,Trk1 ip igmp exit vlan 200 name "Backup WAN" untagged D24 no ip address tagged F4 exit vlan 2 name "Networking" untagged C1-C2 ip address 192.168.2.254 255.255.255.0 ip helper-address 192.168.3.22 tagged A15,E1-E4,F1-F4,G3,Trk1 exit vlan 3 name "Servers" untagged B6,D22 ip address 192.168.3.254 255.255.255.0 ip helper-address 192.168.3.22 ip forward-protocol udp 192.168.11.255 7 tagged F2,Trk1 ip igmp exit vlan 6 name "IT Support" untagged G4 ip address 192.168.6.254 255.255.255.0 ip helper-address 192.168.3.22 ip forward-protocol udp 192.168.11.255 8992 tagged E1-E4,F1-F4 ip igmp exit vlan 4 name "Printers" untagged A6,B11 ip address 192.168.4.254 255.255.255.0 ip helper-address 192.168.3.22 tagged E1-E4,F1-F4 exit vlan 7 name "Perimeter" untagged B16,G1 ip address 192.168.7.254 255.255.255.0 exit ip route 0.0.0.0 0.0.0.0 192.168.7.1 spanning-tree spanning-tree Trk1 priority 4 ip multicast-routing router pim exit vlan 1 ip pim all exit vlan 6 ip pim all exit password manager Apart from removing a couple of identifying lines (the snmp-server contact and snmp-server location lines), this is the entire config. As you can see, the VLANs are entirely port-based at the moment, with no ACLs - all of that is coming later. The VLANs that don't have IP addresses configured on the switch are meant to be that way, as there are some VLANs I don't want to route. I've eliminated the multicast routing/PIM as a cause, as the problem happens even with that section removed. Oh, and yes, VLAN 1 is meant to have a 192.168.8.0/22 range rather than /24. I know it looks odd but it's meant to be that way, and again, the problem still occurs if it's a /24 range. Here's the routing table, which to me looks as expected: IP Route Entries Destination Gateway VLAN Type Sub-Type Metric Dist. ------------------ --------------- ---- --------- ---------- ---------- ----- 0.0.0.0/0 192.168.7.1 7 static 1 1 127.0.0.0/8 reject static 0 250 127.0.0.1/32 lo0 connected 0 0 192.168.2.0/24 Networking 2 connected 0 0 192.168.3.0/24 Servers 3 connected 0 0 192.168.4.0/24 Printers 4 connected 0 0 192.168.6.0/24 IT Support 6 connected 0 0 192.168.7.0/24 Perimeter 7 connected 0 0 192.168.8.0/22 DEFAULT_VLAN 1 connected 0 0 192.168.100.0/24 NM 100 connected 0 0 CPU and memory usage seems fine: typically more than 50% free memory, and CPU fluctuates between 2-40%, but not seen it go higher. I'm about a day away from calling in a consultant at this point, which will make me extremely grumpy. If anyone here can give me a clue, it would be very very welcome.
-
Office 2010 was the product that led me down the route of System Center Essentials, which I then canned in favour of the free Local Update Publisher, which lets you install almost anything using your existing WSUS server. Once you have it configured, you will be able to install pretty much anything you used to install using RM Package Manager. Once you've converted, you will never look back: I now do literally all my software installations using LUP, with nothing done via Group Policy any more. It's that good.
-
This sounds very dodgy indeed. On my account, the printers are listed identically in both places, and HKCU is supposed be be nothing more than a pointer to the correct HKU\SID node.
-
I use the free Specops Password Policy Basic to manage our fine grained password policies. You get added to their mailing list and every so often they'll try to sell you their more advanced tools, but it's well worth it.